Exposing Flaws in Standard Visual AI Evaluation and Introducing a New Benchmark
AI TIMES ·
✦ AI Summary
According to AI TIMES, a research team led by Professor Yoo Jae-jun at UNIST on October 1 pointed out structural flaws in the standard evalu…
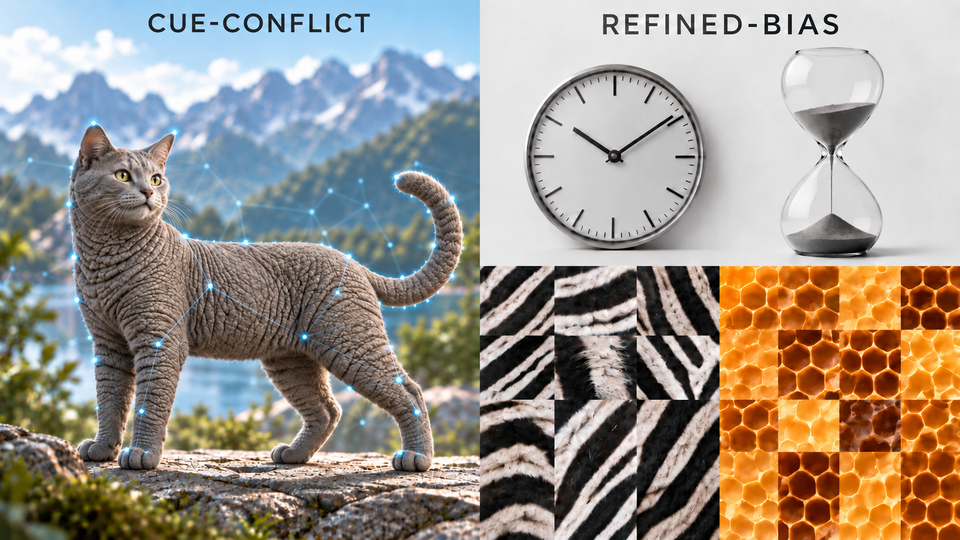
According to AI TIMES, a research team led by Professor Yoo Jae-jun at UNIST on October 1 pointed out structural flaws in the standard evaluation method used to assess visual AI's object-recognition abilities and introduced a new benchmark. The team said the existing approach could distort results because it relied on ratio-based scoring, biased synthetic images, and a limited answer range in studies selected for conference spotlights, which account for only about 1.3% of the total 10,473 submitted papers. In particular, the main problem was that cases where a model saw shape well but missed texture were lumped together with the same preference as cases in which shape ended up being weighted more heavily. The new standard therefore scores how well shape and texture are recognized separately, and it also refines image composition and scoring methods to look more directly at how each type of information is used. When tested again under this framework, high-performing models were found to rely more actively on both shape and texture rather than following just one. The research team said that unless the evaluation yardstick itself, which has influenced development directions so far, is revised, model interpretation and improvement could also go off course, and it explained that the new standard could be a starting point for more accurate diagnosis.
Perspective
The significance of this study is that it shows the competition to build better models is now shifting from model architecture or training scale alone to the question of what standard is used to judge performance. Because the evaluation used like a standard had already pushed development directions, correcting its flaws could help the industry move away from overemphasizing specific tendencies and place greater importance on how much information a model actually uses. In the end, its impact is not small because it is an effort to rebuild the link between performance interpretation and model improvement.
This perspective is BizCrush's own commentary and is not part of the reporting by AI TIMES.
This article was produced with the help of an automated content generation algorithm.
Source: AI TIMES
View originalThis article was summarized and organized by BizCrush based on the original article from AI TIMES. For exact quotations and full details, please refer to the original article.